Directus in practice

This walkthrough follows the features this site actually uses.

Most of it is straightforward. The hardest part to grasp is decisions and roles; that logic gets tangled up with security tokens and the like, so it's worth thinking through carefully.

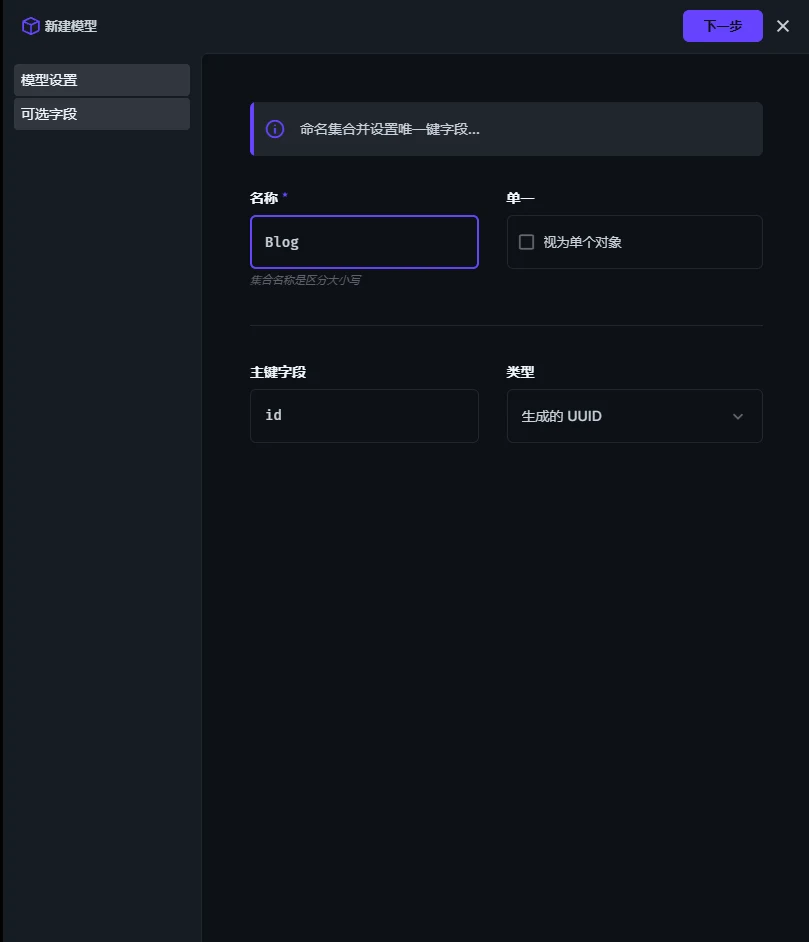
1. Creating the collection
E99e5401 A98e 498a 8a8e 71f9deff0b8d (1)

Ones I strongly recommend ticking

  • Created at (date_created):

    • What it does: automatically records the year, month, day, hour and minute the article was created.

    • Why I recommend it: a blog obviously needs to show a publication time, right? Tick this and every new article gets a timestamp automatically; the frontend can simply read and display it.

  • Updated at (date_updated):

    • What it does: whenever you edit the article, the field is updated to the current time.

    • Why I recommend it: the frontend can show "last modified on 2026-06-05".

2. Ones that depend on your needs

  • Archived:

    • What it does: it works like a draft box, or a soft delete.

    • Why pick it: if you have written half an article and don't want to publish it, or you want to take an article down without deleting it for good, tick this. On the frontend you just filter out archived articles when you call the API.

  • Sort:

    • What it does: lets you drag articles in the admin to change their order.

    • Why pick it: for a blog, sorting by date descending is usually enough, so you can leave this unticked. But if you later build a Product collection, I would strongly recommend ticking it, because products often need their display order adjusted by hand.

3. Ones you can skip (multi-user collaboration)

  • Created by (user_created) & Updated by (user_updated):

    • What they do: record which admin account wrote or changed the article.

    • Why skip them: this is your personal blog and website, and you are the only person using the admin, so there is no need to record who wrote what. If a company has several people managing the backend, then these are essential.

2. Creating fields

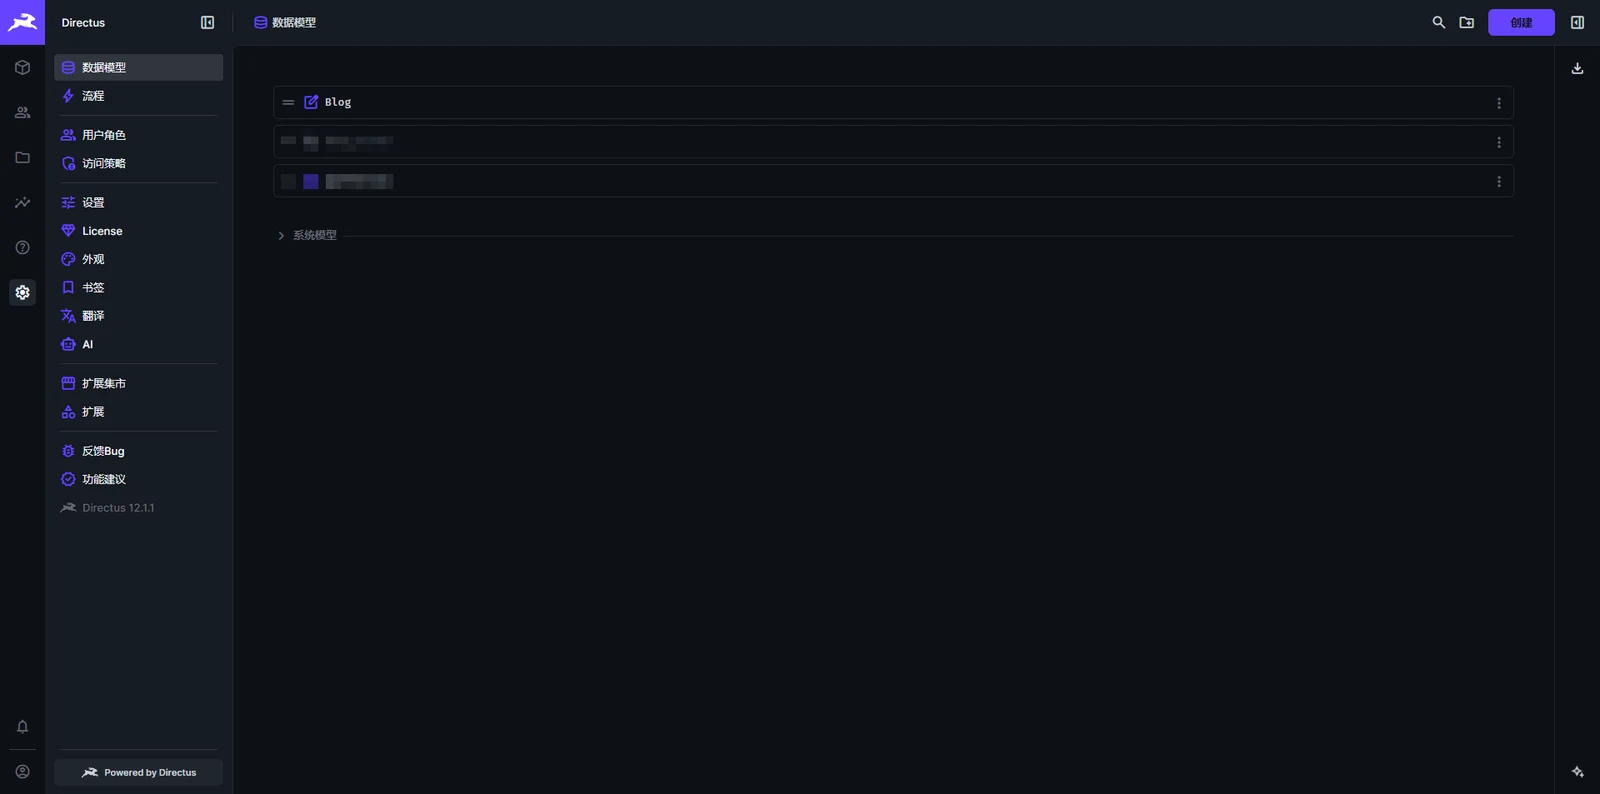
In settings you can see your model (table)
Screen Shot 2026 07 11 200241 736

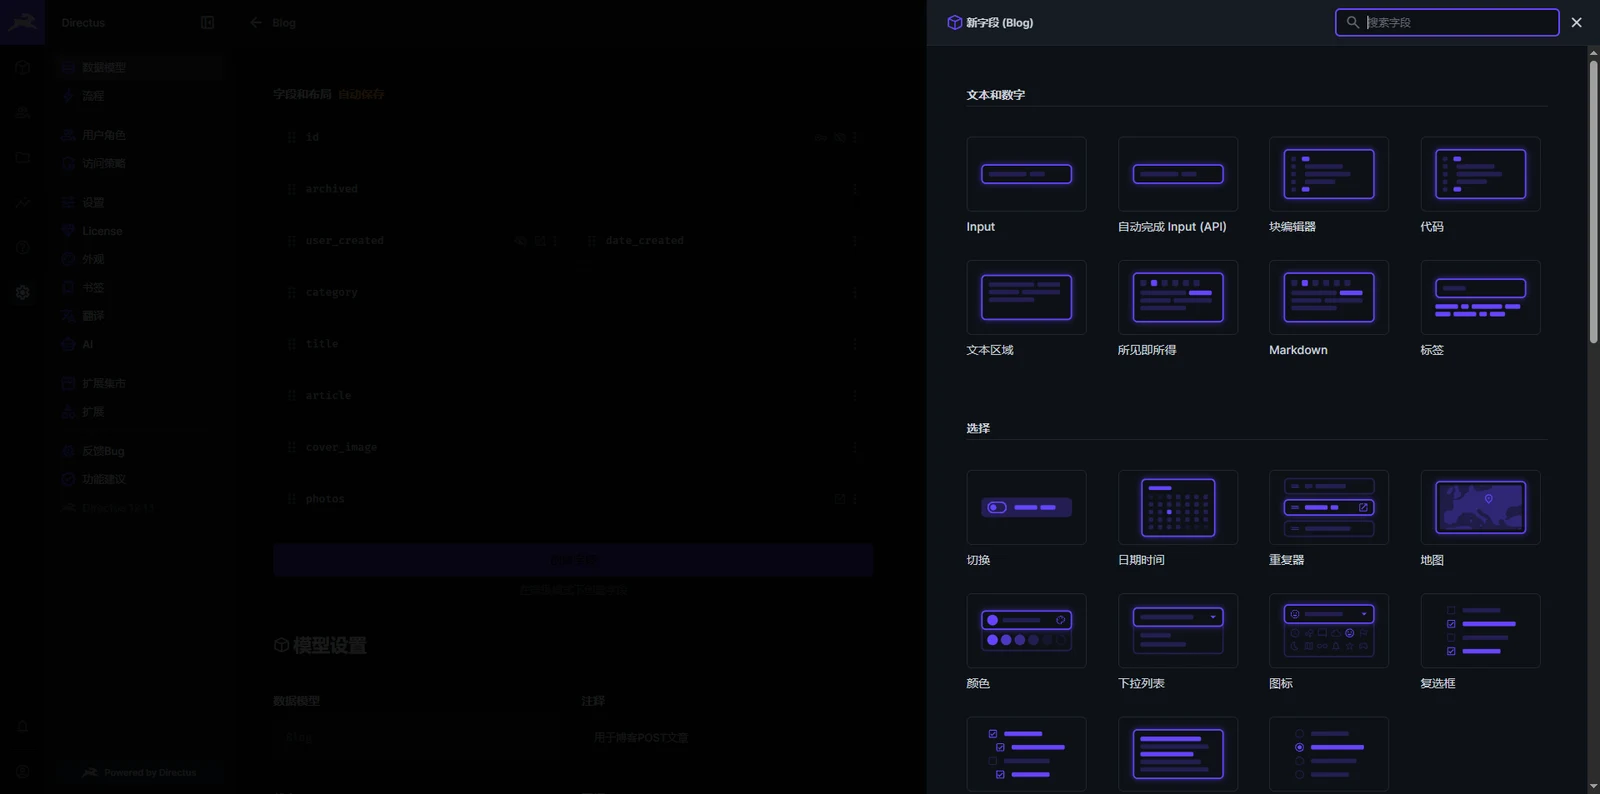
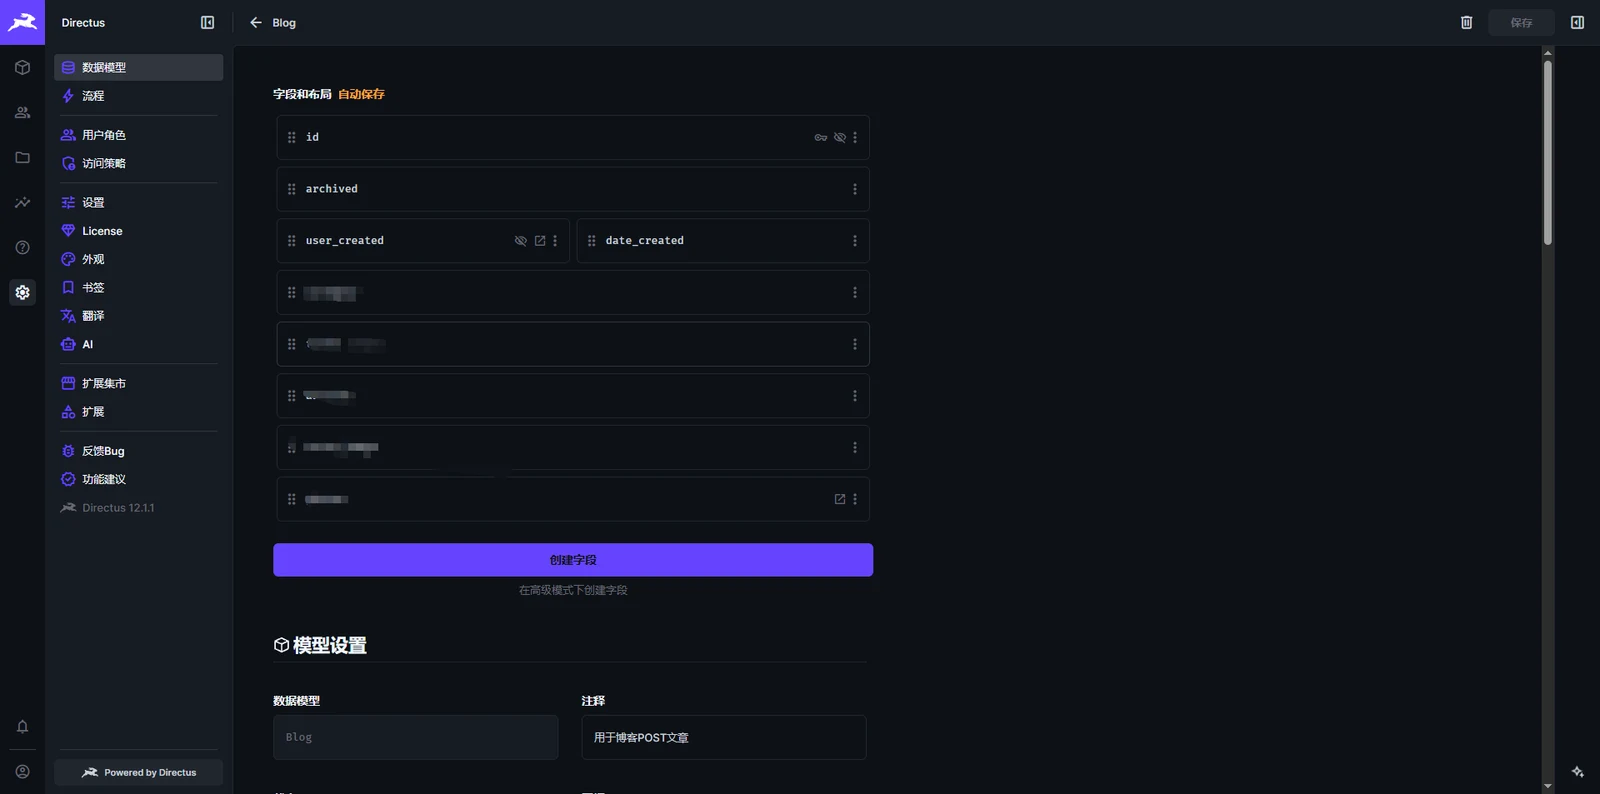
Open the table and you can set up its fields
Screen Shot 2026 07 11 200611 127

Simple enough, right? You don't even have to set the field types yourself — just pick one. You will still want to read up a little on the specifics.

For example, my article category field `category` uses a dropdown list 

The Chinese translation is hard to make sense of; I would still suggest using the English interface.

For example, the rich text editor is labelled "what you see is what you get", which is literally WYSIWYG — no idea how they decided to translate it that way.
Screen Shot 2026 07 11 201036 260

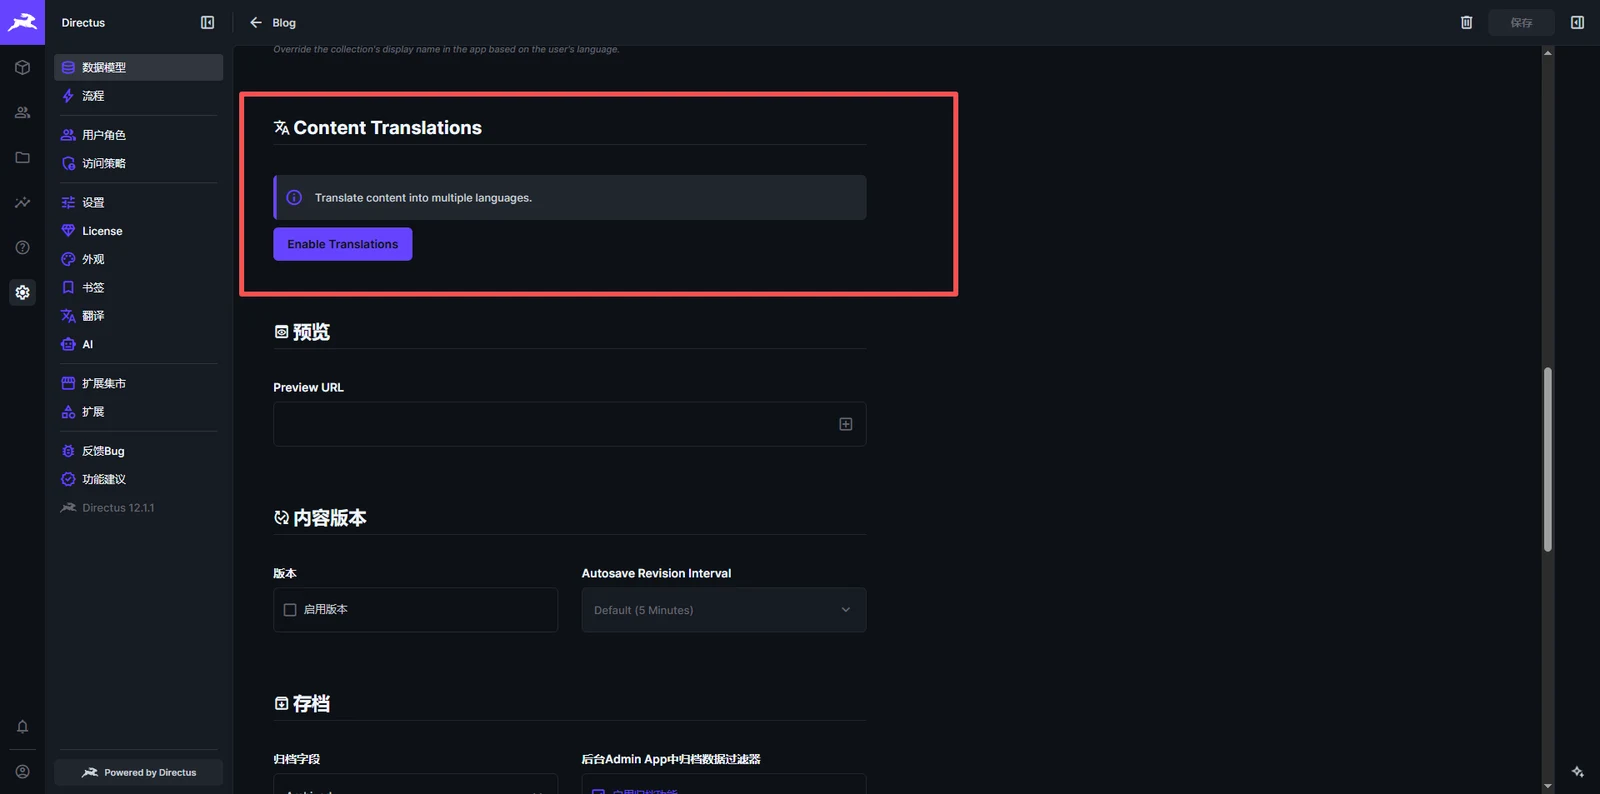
Below that it will usually offer you a Content Translations option

That is easy enough to understand too

The body text is 你好

Underneath it you write the translation, Hello

Two languages, two codes: zh and en

When the interface has a translation button, Chinese requests the content under zh and English requests the content under en
Screen Shot 2026 07 11 201843 307

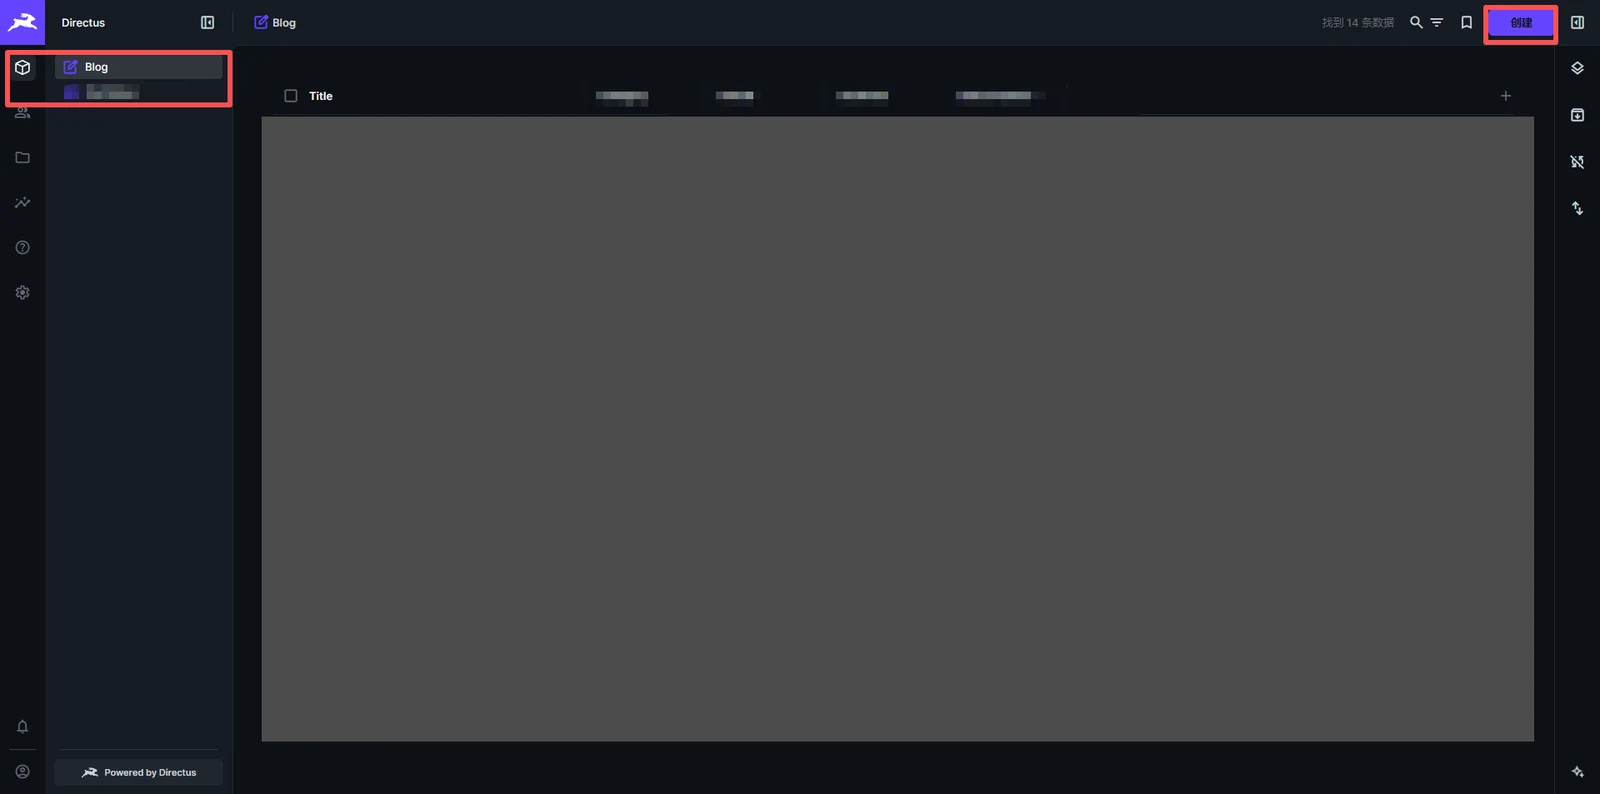
Once it is created, save it and you can start adding fields in the content view
Screen Shot 2026 07 11 202135 735


2. Opening up API read permissions (the important part)
 

860c8cb7 86d4 4694 8890 4005f940e729


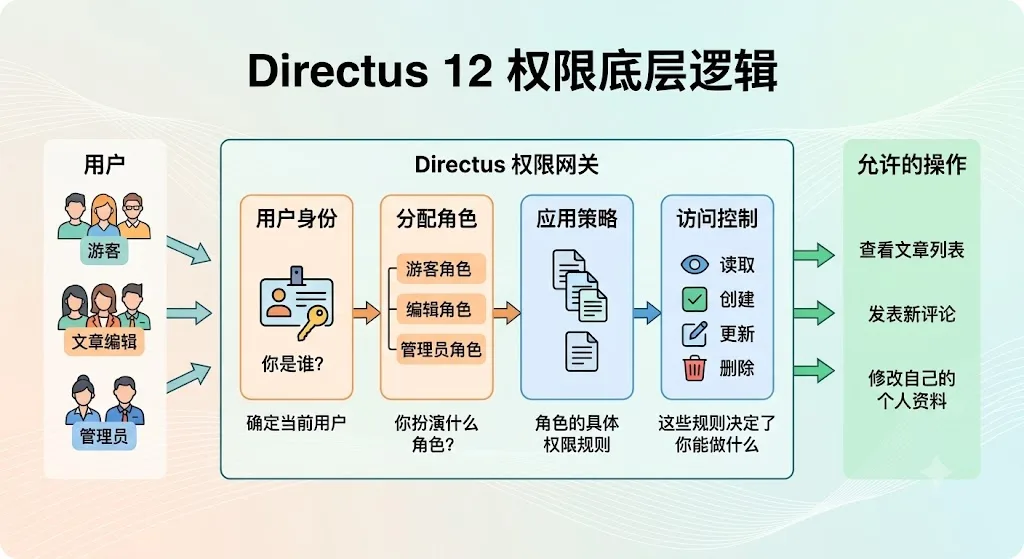
The logic is easy to grasp:

1. What role (identity) are you?
2. Given your identity, what are you allowed to do? (the policy applied)

For example, a visitor hitting the API (user identity) only has permission to view (the applied policy), while an admin user has update and delete permissions through the API.
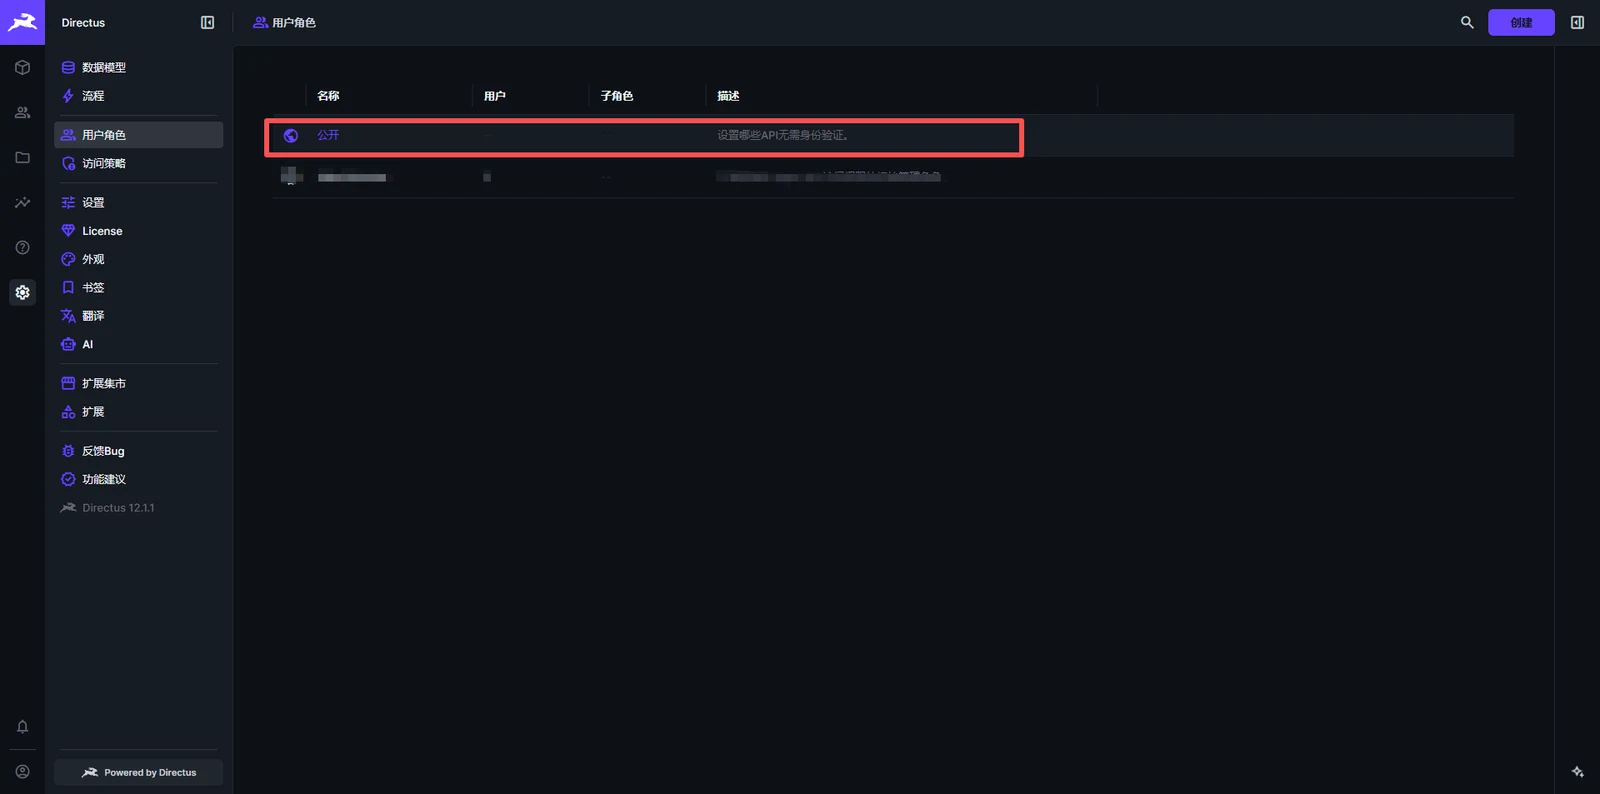
Screen Shot 2026 07 11 203324 792

Inside the user roles there is a default "Public" role

The note also says it does not need token verification
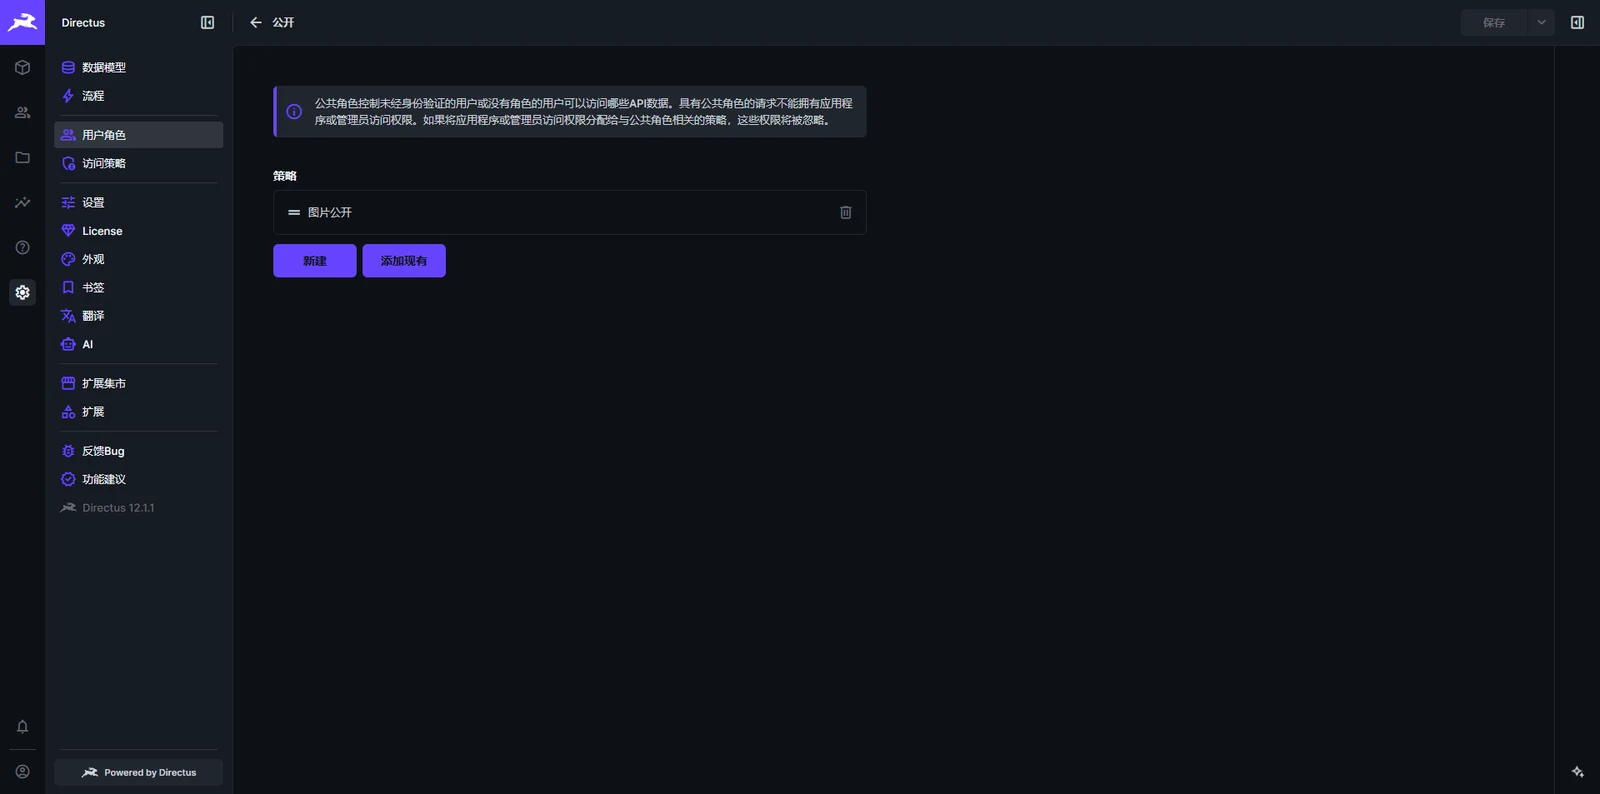
Screen Shot 2026 07 11 203416 951

Click into it and you will see the "Public" role has an "Images public" policy

I set that up myself, because if images also required a token to fetch, it would be very easy to leak your token. I really would not recommend doing that.

3. API links
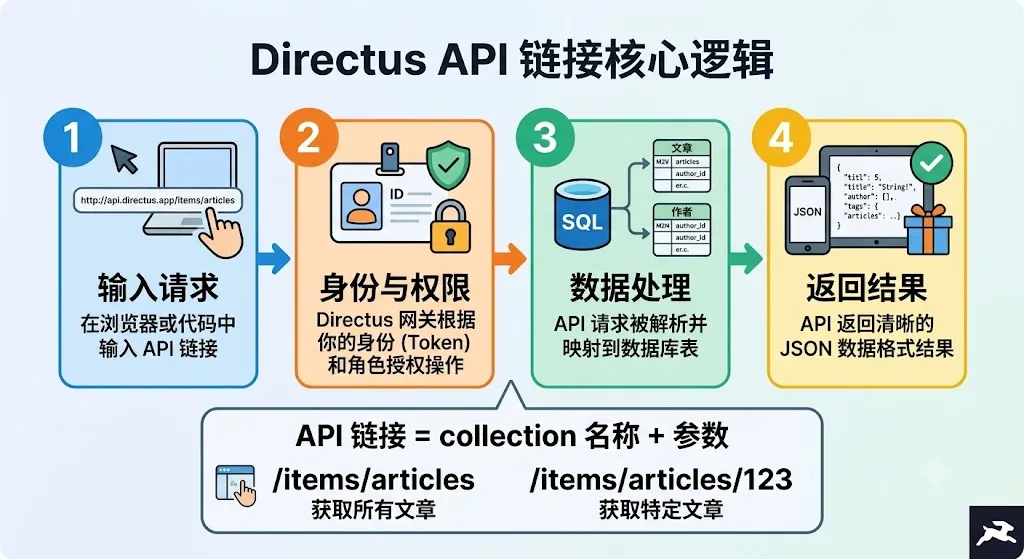
39a79ca1 1910 4edb Bb8f 814213939322

Put simply

You created the blog table

Your domain/items/table-name gives you all the JSON data from that table
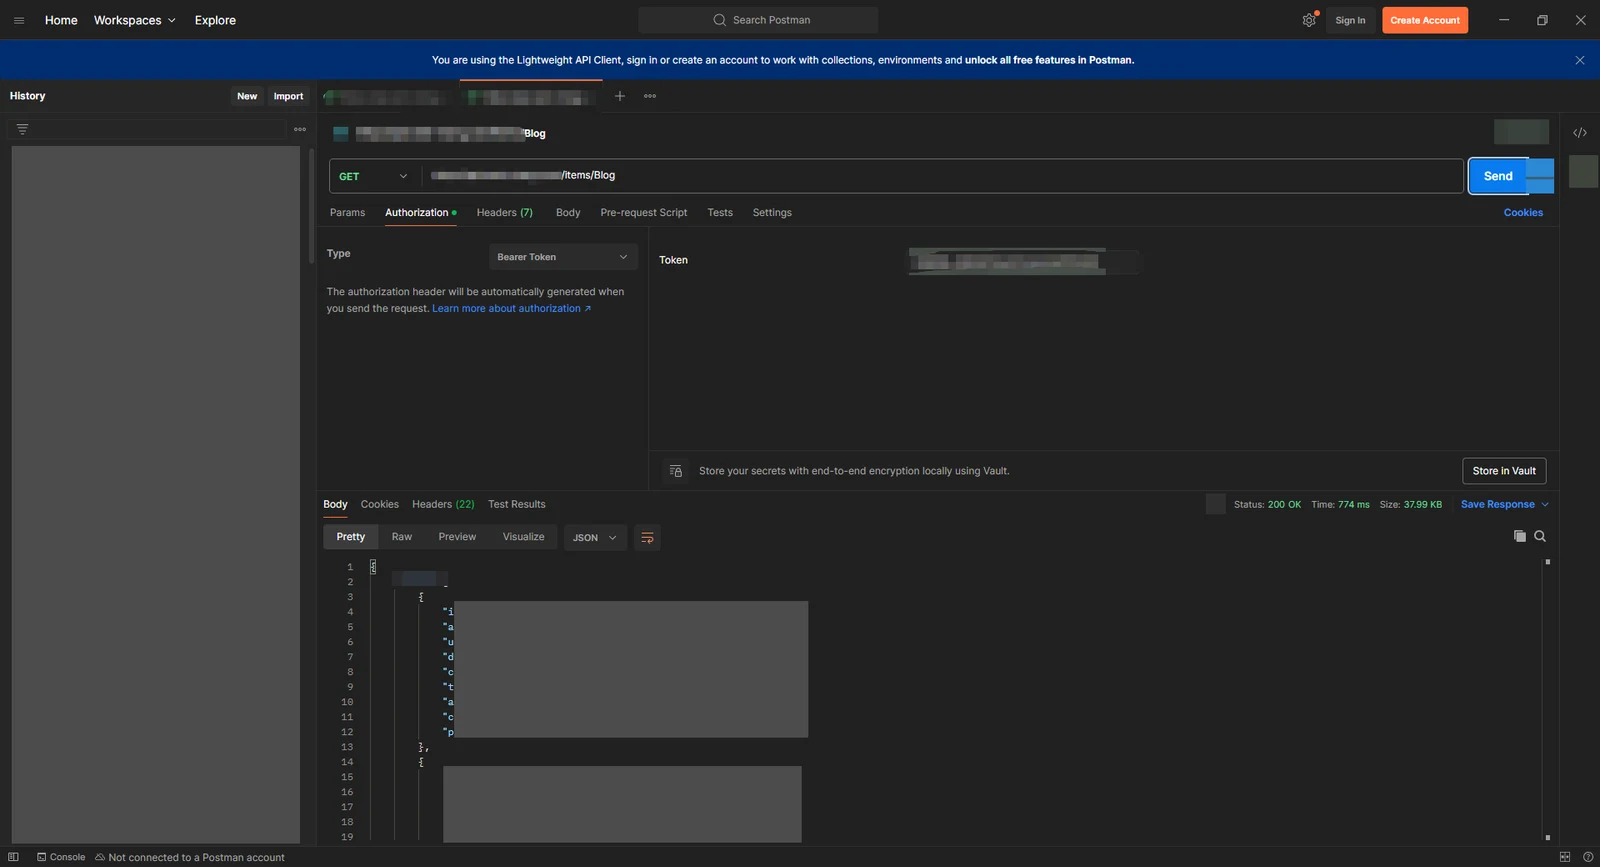
Screen Shot 2026 07 11 204557 757

There are other tricks too

For example

https://your-domain/items/table?filter[archived][_eq]=false&fields=id,title,article,categore

That is how you filter data

See the Directus documentation for the details

The logic is very simple


4. How do you add a security token?

This is easy to set up too

Step one: make a "key" in Directus and lock it

It is quite convenient, compared with how it used to be done

It only takes two steps

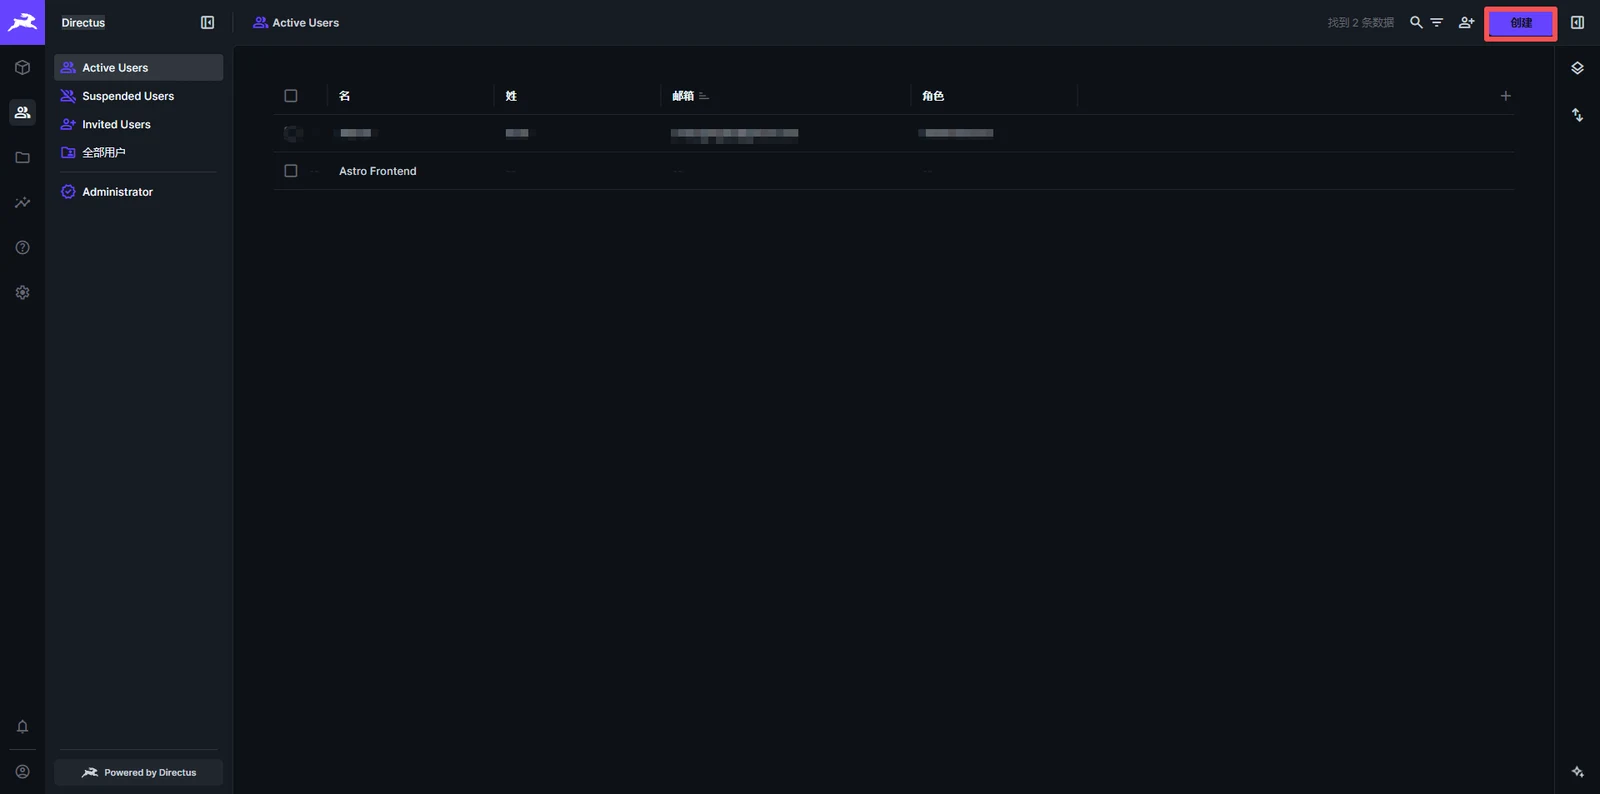
1. Create a user and generate a token

  1. Log in to the Directus admin

  2. Click User directory in the left menu

  3. Click + Create user in the top right

  4. Fill in any name, Frontend for example. No email or password needed

  5. The most important step: scroll down on the user profile page and find the Token field

  6. You will find that saving the user generates a token automatically; save it, then come back and it will be there
WeChat image 20260711205442 26 28

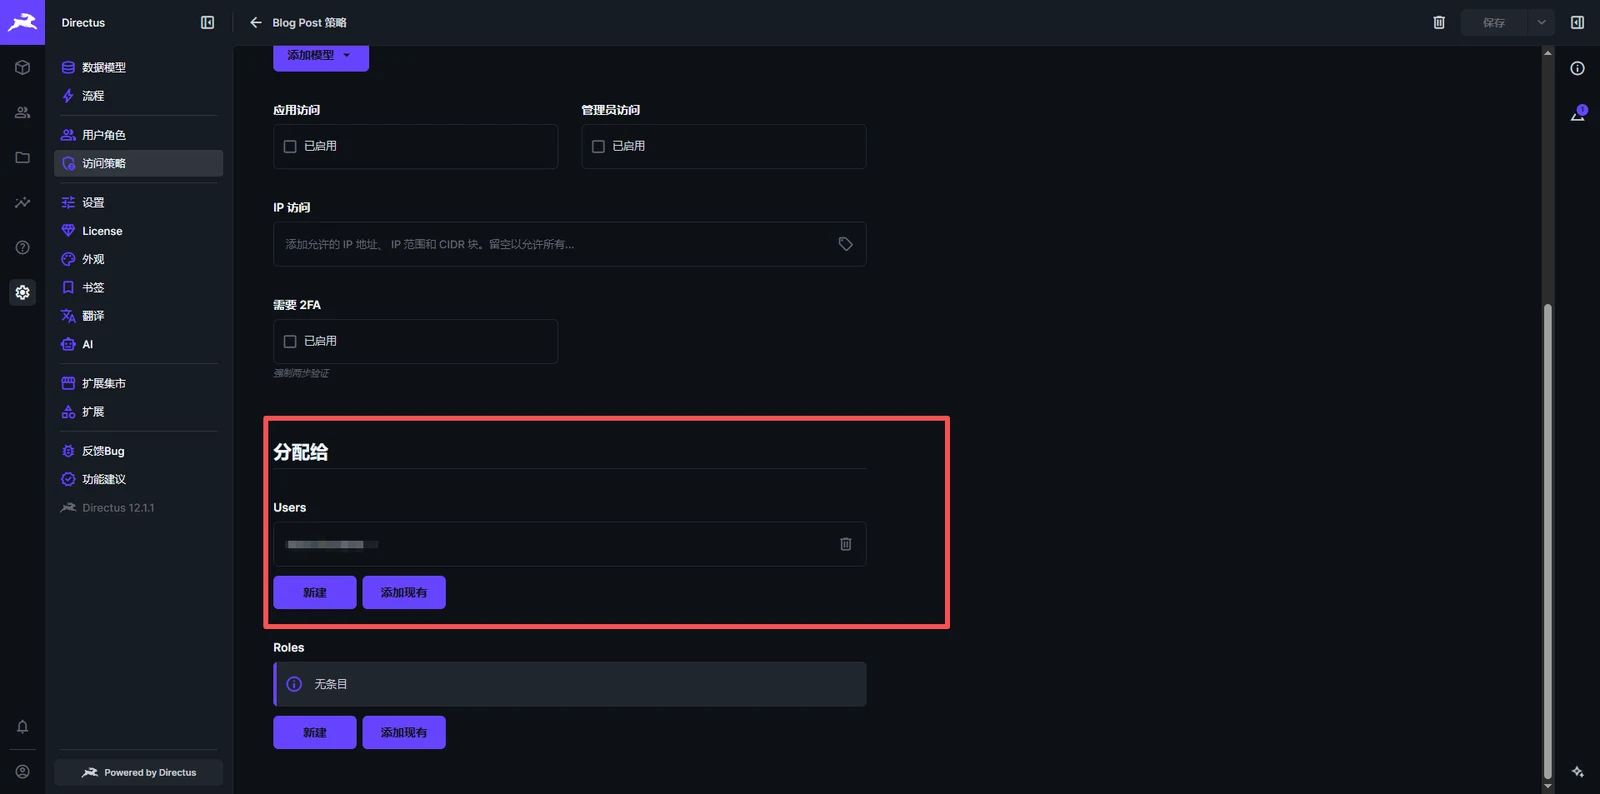
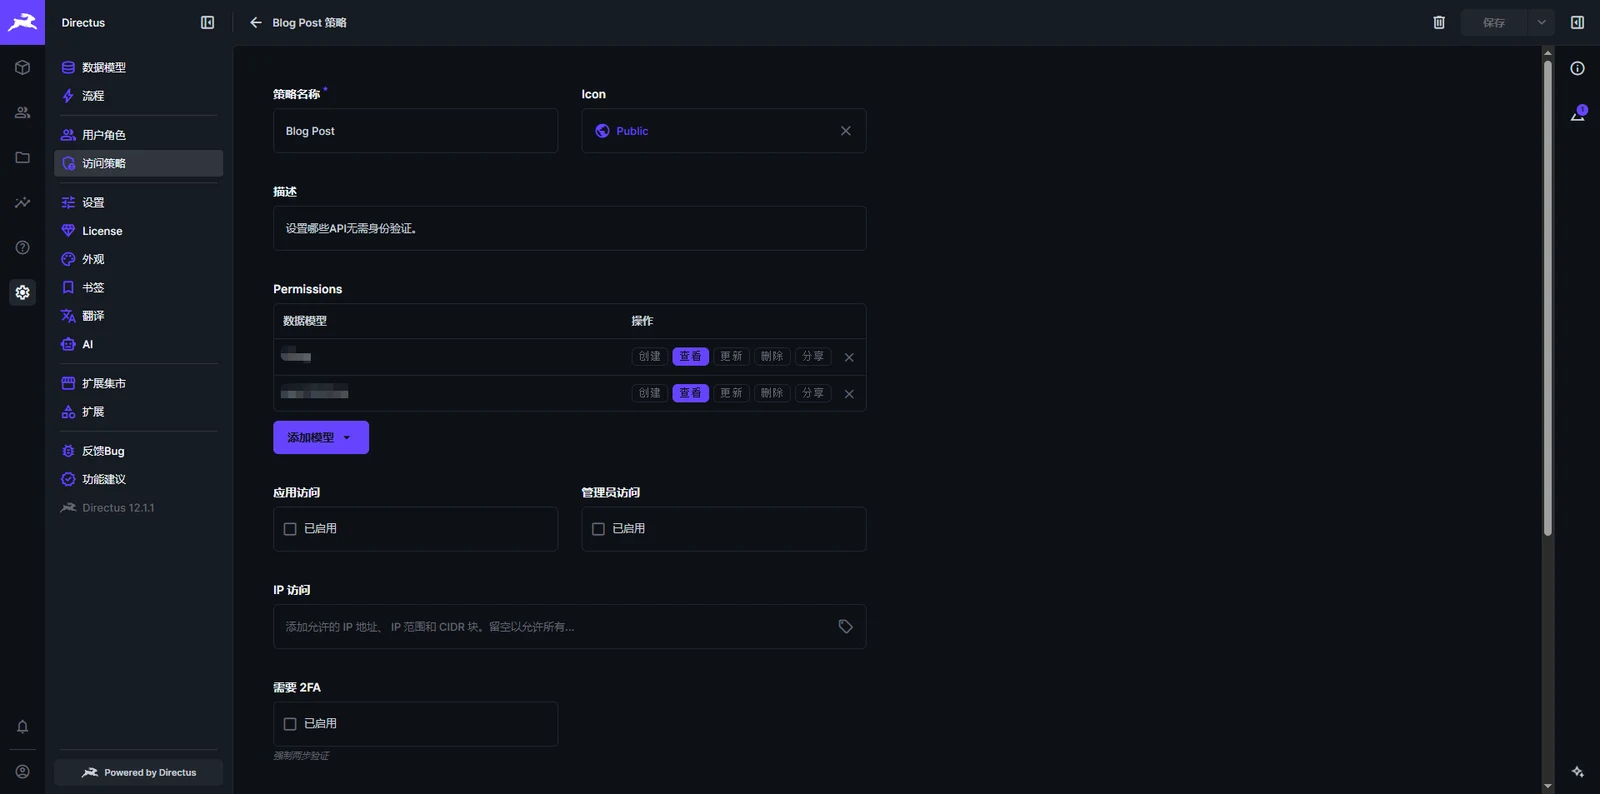
2. Create a matching permission policy

  1. Set the permissions for the relevant tables
  2. Assign the account you just created at the bottom
Screen Shot 2026 07 11 205949 086

Screen Shot 2026 07 11 205925 261

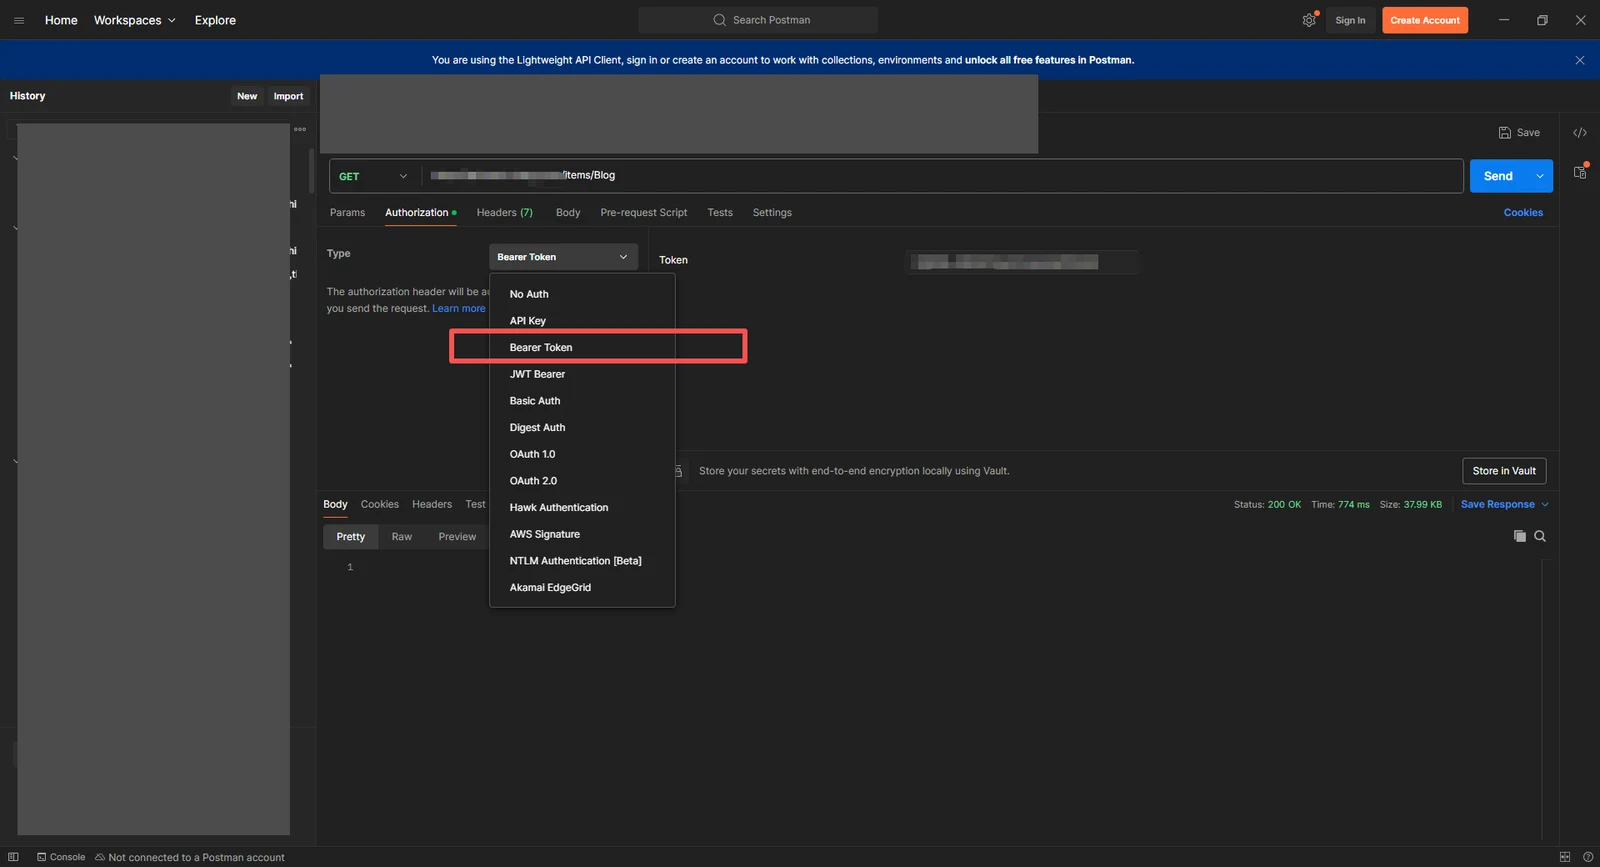
Then you can test it in Postman

WeChat image 20260711210239 27 28


That's it


Related posts

Building an industrial website with Astro

I built LIANXIN's industrial machinery website with Astro. It has a product catalogue, a factory showcase, and Directus-powered news and an AI product assistant. On a site like this, a lot of decisions come down to one question: which content should be handed straight to the user, and which features should only start up when they are actually needed. Machine photos, specification tables and copy are better generated ahead of time; news has to update at any moment; carousels, enquiries and video each have their own interactions. Once those boundaries are clear, the implementation goes much more smoothly. The factory poster the site uses now. Source: the LIANXIN website. Pages first, interactions on demand One thing I like about Astro is that it lets me organise a page starting from HTML. Product copy and images render first; React comes in only where state and events are needed. Having the React integration installed does not mean turning the whole page into a client-side app. The site navigation uses client:load, so it activates as the page loads; the product carousel uses client:visible, loading and hydrating when it enters the viewport. Both approaches output HTML first; the difference is when the component starts running in the browser. For the exact timing, see Astro's client directives documentation. FAQ goes further and uses a client:interaction directive registered by the project itself. It starts loading on hover, touch or keyboard focus. There is a small trap here: a user might click a button before loading finishes, so the directive holds that click and replays it once the component is ready. Ordinary links navigate as usual. Saving JavaScript is fine — just don't save the visitor's first click. News takes a different route. The list and detail pages read Directus per request, while the latest news on the homepage is left to server:defer. The homepage returns its main body and placeholders first, and the news block requests its HTML separately afterwards. That way a slow CMS response does not hold up the whole page. This part needs a server, so I run the site with the Node adapter in standalone mode. Astro's official diagram showing how a static page and a dynamic block get their content separately. Source: Astro 5.0, &copy; Astro; this is not a diagram of this site's deployment. Products and the AI share one source of truth The products come in several series, and each model has photos, specifications and application notes. If all of that is scattered across pages, changing one specification means hunting down every place it appears. I organised the products into TypeScript data and let the pages read from it. The model detail pages reuse a single template and generate their routes with getStaticPaths(). Here is the path generation from the detail page, with imports and the page template omitted. export function getStaticPaths() { return products.map((product) => ({ params: { category: product.category, slug: product.slug, }, props: { product, category: getCategory(product.category), }, })); } The specification tables read that data, and the Product structured data on the page reads it too. The AI product knowledge is generated from the same source, so the assistant isn't reciting an old version after the website has been updated. The data model keeps explicit fields for model, category, images and specs; the pages only display them. The AI backend is a separate Cloudflare Worker. It searches for material based on the model, aliases and current page in the question, picks at most six documents to hand to DeepSeek, then checks whether the source IDs attached to the answer belong to that batch. The browser gets the answer and the matching on-site links; the model key stays in the Worker. This retrieval approach is small in scale and simple in its rules, which suits this set of products. It can constrain where the sources come from; it cannot guarantee that every sentence the model produces is correct. Specific selections and quotations still need a human to confirm. Also, sharing a source file does not mean it goes live automatically. After product data changes, both the main site and the assistant Worker need to be rebuilt and deployed; that step is easy to miss. Images are about composition, video is about timing Industrial equipment is long to begin with. Add a few heavy frames around it and the machine you can actually see gets smaller and smaller. For product photos I use object-fit: contain to keep the whole shape; the title, selling points and buttons sit beside it, giving the image enough room. The carousel controls stay on either side so you don't have to scroll down to change slides. A showcase image of the IBM 80E, with the machine's outline kept intact. Source: the corresponding LIANXIN model page. For the homepage poster I prepared landscape and portrait versions and switch between them with <picture> using max-aspect-ratio: 1/1. The choice follows the shape of the viewport, so a portrait tablet still gets a portrait composition. The first poster loads eagerly and the rest are lazy-loaded. The copy currently lives inside the posters too, which buys more direct control over layout at the cost of re-exporting images whenever the text changes or a language is added. Video is handled more bluntly. The factory introduction shows a cover first and keeps the video address in data-src, assigning it to src only when the visitor clicks play. Someone who is just browsing the page doesn't end up downloading a few minutes of video along the way. The key action in the playback function looks like this, with the loading hint, timeout and error handling omitted. if (!video.hasAttribute("src")) { video.src = video.dataset.src!; } void video.play(); Native <video> plus one custom element to manage playback state is enough here. Slow networks get a loading hint; failures get a retry button and a link to the original video; leaving the component aborts the event listener and pauses playback. At least the user can tell what happened after they clicked, and has a way to carry on.

Sep 7, 2026·Tech
Building an industrial website with Astro

Fatigue detection on Android

I built an Android fatigue reminder app that watches for closed eyes and an open mouth through the front camera and does the detection on the phone itself. Once the model is wired in, the real work is the judgement that comes after it. Alert on a single blink and the reminders quickly turn into noise; keep showing normal when the camera can't see anything and you mislead people about what the system can do. First, measure the eyes and the mouth The project uses ML Kit Face Detection, with the model bundled into the APK so there is no download to wait for after installation. It provides the face contour, mouth landmarks and eye-open probabilities, while the fatigue rules are implemented in the app. That keeps detection and judgement separate: changing a duration does not mean touching the camera code. The model extracts face information; when to raise a reminder is decided by the rules afterwards. The illustration comes from Google's ML Kit documentation. The eyes use EAR, the eye aspect ratio. Take six points from the eye contour, add the two upper-to-lower eyelid distances, and divide by twice the eye width. The formula is EAR = (one eyelid distance + the other) &divide; (2 &times; eye width). When the eye closes, the height shrinks and EAR usually drops. Working with a ratio reduces the effect of how far away the face is, but side angles, occlusion and landmark drift still affect the result. Google ML Kit's official contour example; click the image to see the original. Keep the eyelid and lip points straight — the MAR in this article measures the outer lip edge. This is the official example, not a screenshot from this app.Image source. The mouth uses MAR. In this project it is the distance from the centre of the upper outer lip to the centre of the lower outer lip, divided by the distance between the mouth corners. The formula looks simple, but where you put the points is not something you can wave away. Measuring the outer lip and measuring the opening inside the mouth give you different numbers; copying a threshold off the internet is quite likely to be wrong for your case. I also kept ML Kit's eye-open probability and OR it with EAR: if either path meets the condition, the matching timer starts. The probability path requires valid values for both eyes. That lets both signals take part on their own, but it also means an error in one path can trigger a candidate; they come from the same detector, so they are not two independent pieces of evidence. The mouth is judged separately, so when the eyes are temporarily unusable a valid MAR can still take part. Crossing a line once does not count as an action yet A single frame only tells you how narrow the eyes are and how wide the mouth is at that instant. Separating a blink, a brief mouth opening and a sustained action needs time on top of that. The current ordinary eye-closure condition is EAR &le; 0.22, or either eye below 0.35 when both probabilities are valid, held for 800 ms to enter WARNING. The stronger condition is 0 < EAR < 0.17, or both probabilities below 0.35, held for 400 ms to enter DANGER, which takes priority. The yawn candidate uses two thresholds. The timer only starts once MAR passes 0.40, and after that it keeps running as long as MAR stays at or above 0.35, reaching 800 ms cumulative before it reminds you. If the value wobbles between 0.41, 0.39 and 0.42, a single threshold would reset the timer over and over. The mouth is still open, but the timer has closed itself for you. The key branch in the code is only a few lines. Below is an excerpt from the decision logic, with the invalid-value checks and the timing that follows omitted. val yawning = mar != null && if (highMarStartMs == null) { mar > config.marYawnEnterThreshold // 0.40 } else { mar >= config.marYawnExitThreshold // 0.35 } The time comes from the camera frame's timestamp, not from the moment the model callback finishes. Otherwise a slower inference this time and a faster one next time would be mixed into the action duration. When two valid observations are more than 1.5 seconds apart, the unfinished timer is cleared and starts again from the current frame. With no frames in between, the system has no basis for joining two mouth openings into one continuous action. That interval is an engineering trade-off too; it cannot prove what happened between samples. If it cannot see clearly, don't keep reporting normal Besides NORMAL, WARNING and DANGER, the judge keeps a DEGRADED state. When there is no face, when all the eye and mouth signals are invalid, or when a dark frame or a camera error is detected, it clears the unfinished timers and shows the reason it currently cannot detect reliably. NORMAL also only means that the current valid signals have not met the reminder condition; it must not be read as the driver being alert. On the camera side, acquireLatestImage() takes the newest analysis frame, and if the current session already has an inference task running, the new frame is released immediately so the app does not fall further and further behind. When detection stops or the app goes to the background, the session number increases; an old task that returns late must not overwrite the newer state. After detection restarts, the timing starts again from the new frames as well. Sound and vibration are only triggered by DANGER; WARNING just updates the interface. The danger alert has a cooldown of about two seconds and is sent through a SharedFlow that does not replay historical events; the interface only receives it while resumed in the foreground, so pausing stops the prompts. Otherwise, coming back to the app would suddenly fire a reminder about something that already happened. As it stands, this implementation is still a research prototype with fixed thresholds and no personal calibration. A sustained open mouth can also come from talking, and the eye-open probability is limited by the face angle. On the phone side I have only verified installation, the camera pipeline and foreground/background switching on an emulator; real-person detection, overlay accuracy, and the sound and vibration still need testing on a target device. The more worthwhile next step is to record normal speech, brief mouth openings, natural yawns and closed eyes, and use them to check false positives and misses in a static setting; this prototype is not yet a road-validated driving safety system.

Sep 7, 2026·Tech
Fatigue detection on Android

A few pitfalls in MediaPipe hand gesture recognition

This time I built an offline hand gesture recogniser on a LubanCat 3, running Android 14. The camera sees a hand, draws the skeleton, and when you make an OK sign it automatically saves a screenshot with the skeleton drawn on it. The model is Google's MediaPipe. It already finds 21 hand keypoints and classifies seven static gestures. What is left for you is the camera, the screen coordinates, and turning recognition results into actual actions. Use the model as it comes The Android side is written in Kotlin, the camera uses CameraX, and recognition uses MediaPipe Tasks. These are the dependencies. def cameraxVersion = '1.4.2' implementation "androidx.camera:camera-core:$cameraxVersion" implementation "androidx.camera:camera-camera2:$cameraxVersion" implementation "androidx.camera:camera-lifecycle:$cameraxVersion" implementation 'com.google.mediapipe:tasks-vision:1.0.0' Put the official model into app/src/main/assets, point the recogniser at that file when you create it, set the running mode to LIVE_STREAM and take results from the callback. The official Android example already wires it up completely; reading that is faster than guessing from an empty project. The model ships inside the APK and inference runs on the board, so at runtime it only needs camera permission. The base image comes from MediaPipe's official test image; this is the board-side output from this project. The red dots are joints, the blue lines mark the thumb, and the remaining connections are green. Don't open two camera streams The usual CameraX setup uses Preview to show the image and ImageAnalysis to feed frames to the model. On the firmware for my RK3576 board, opening both at once hangs. In the end I kept a single ImageAnalysis and shared it between preview and recognition. After getting a 1920&times;1080 image, I handle the row stride, scale the longest side down to 640 pixels, then rotate and mirror it consistently before feeding it to the model. The frame strategy is KEEP_ONLY_LATEST: if it cannot keep up, drop the old frames instead of queueing recognition. The current code also throttles submissions to at least 100 ms apart, so the submission rate tops out at roughly 10 frames per second; what you actually see still depends on the inference callback. Always close ImageProxy when you are done, including on skipped frames and error paths. If the buffer is held, the camera may simply stop producing frames later. Also, on the board, CAM0, Android's Camera ID 0 and /dev/video0 have to be checked separately. This project checks the physical m00_ module, the logical ID 0 and the current firmware's FRONT attribute together, and stops if the conditions are not met. That mapping only holds for the board and firmware I verified. Why the skeleton drifts You have to look at both coordinates and timing. On coordinates: the model returns normalised keypoints, but the preview uses centerCrop. The image is scaled up first and then cropped to the display area. Multiplying keypoints by the screen size directly obviously will not line up. To project keypoints onto the screen you have to use the same scale and crop offset as the preview. Below, x and y are the normalised coordinates from the model, and srcW, srcH are the width and height of the model's input image. scale = max(viewW / srcW, viewH / srcH) offsetX = (viewW - srcW * scale) / 2 offsetY = (viewH - srcH * scale) / 2 screenX = x * srcW * scale + offsetX screenY = y * srcH * scale + offsetY These divisions need floating point. Rotation and mirroring are also handled before inference so that the preview and the model do not each compute their own direction. On timing: the hand has already moved away and the previous frame's result comes back. Overlaying an old skeleton on a new image is a bit like an out-of-body experience. My fix is to take the matching input image out of the result callback and update the interface with this frame's keypoints at the same time. The image and the skeleton have to belong to the same frame. The cost is that the display waits for the recognition result, and preview smoothness suffers with it. There is another condition that is easy to miss. A classification result of None only means no supported gesture was recognised. As long as the keypoints are there, keep drawing the skeleton; only clear it when no hand is detected, the result is stale, or the app goes to the background. The OK screenshot needs burst protection None of the official seven classes is OK, so I added a geometric check on top of the existing keypoints: the thumb tip and index tip close together, the index finger bent, and the other three fingers straight. Distances are normalised by palm size and combined with joint angles. With a fixed pixel distance, extending your hand a little further makes the threshold wrong. This uses the 2D coordinates restored from the input dimensions, so it stays consistent with the skeleton on screen. Only then comes the trigger control. Every frame of video can recognise an OK, so if you keep holding your hand up it keeps saving images, and the photo library cannot take that. Condition Current rule Confirm the gesture At least 4 strong matches in the most recent 5 frames, with the current frame matching too, and the window lasting at least 300 ms Lock after triggering Hold the OK sign and only one photo is taken Allow another photo Leave OK for at least 600 ms, and at least 1.5 seconds between triggers Make the trigger condition strict and the hold condition loose, to reduce jitter around the boundary. If sampling breaks for more than 400 ms, the old observation window is cleared. These are the current settings; actual trigger timing still depends on the frame rate. The screenshot composites the current image and the skeleton from the same frame, then saves it as a PNG through MediaStore. Only those two layers are drawn, so the status bar and dialogs do not get mixed in. Encoding and writing to disk go on a separate thread so they do not block camera recognition. What is saved is a composite of the displayed image; the input was already scaled down, so it is not the sensor's original image. This version still runs Delegate.CPU. The RK3576 has an NPU, but an app needs RKNN integration to use it. RKNN's official pipeline includes model conversion and runtime integration, and the pre- and post-processing have to be realigned too; changing one setting will not do it.

Sep 7, 2026·Tech
A few pitfalls in MediaPipe hand gesture recognition
Music